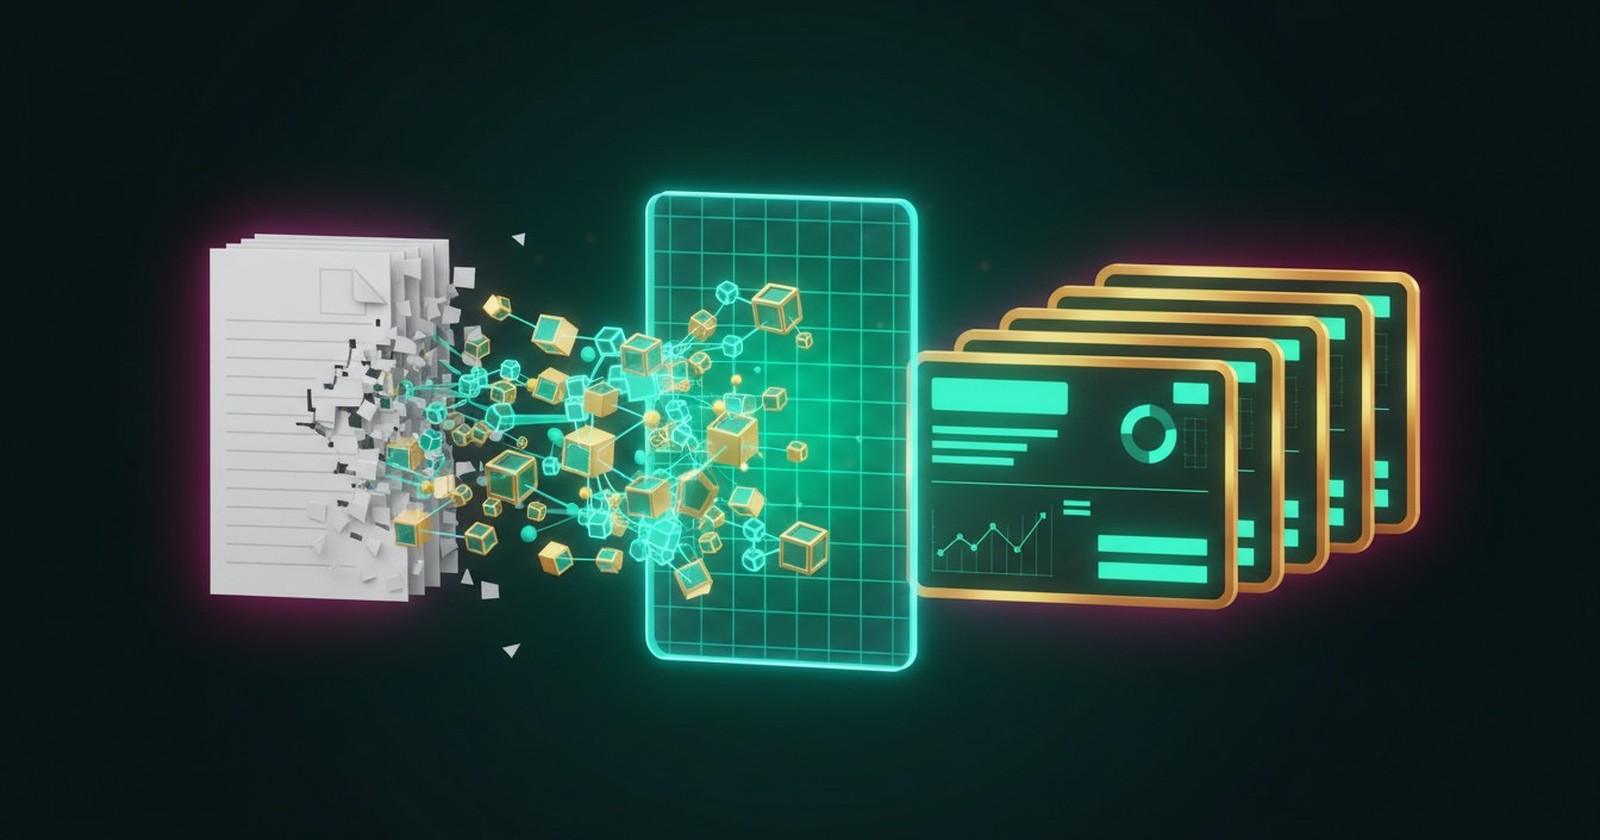
Candidates on our site upload a CV as a PDF and fill in a short form. The form is usually half empty: a placeholder title, two skills, no "about" section. The PDF has everything, but nobody can search a PDF.
So we wanted a pipeline that turns the file into a structured public profile: headline, skills, experience, languages, a short summary. And the profile has to be anonymous. Employers see the person's experience first; the contact details stay hidden until they unlock them.
That second requirement shaped the whole design. An LLM is very good at the first job and cannot be trusted with the second. This post is about the layers we put around it.
Layer zero: getting text out of the file
Most uploads are PDFs with a text layer, and pypdf handles them in a few lines. We read only the first pages, because a CV that needs ten pages to say what someone does will not get better on page nine.
from pypdf import PdfReader

def pdf_text(path: str, pages: int = 6, limit: int = 20_000) -> str:
    try:
        reader = PdfReader(path)
        text = "\n".join((p.extract_text() or "") for p in reader.pages[:pages])
        return text[:limit]
    except Exception:          # broken or encrypted file
        return ""
The surprise was how many "PDFs" are photos. People take a picture of a printed CV with their phone and export it as a PDF. There is no text layer at all, pypdf returns an empty string, and the profile looked empty even though the document was fine.
We added a fallback: if the text layer has fewer than 200 characters, render the first two pages with pdftoppm at 200 dpi and run tesseract with English and Russian models. Both are local binaries, no external API and no keys. If either binary is missing, the module turns itself off and the old behaviour stays.
OCR is slow on a small server (a couple of seconds per page on one vCPU), so it never runs inside an HTTP request. Only the background worker calls it.
Layer one: the model returns JSON, not prose
The structuring step sends the CV text and whatever the candidate typed in the form to Gemini 2.5 Flash. The prompt asks for one JSON object with fixed keys: title, location, experience_years, skills, about, languages, employment_history, education, desired_format, relocation and a few more.
Three details in the prompt mattered more than the rest:
- A fixed "today". The first line says what the current date is and that dates in this and the previous two years are past or present. Without it the model kept flagging recent jobs as "future dates" and marking good CVs as suspicious.
- Bounded fields.
aboutis 400вАУ900 characters, third person.skillsis 8вАУ20 items, most relevant first, no soft-skill filler.desired_formatis one of three allowed values. Bounds make the output easy to validate later. - A self-assessment. The model returns
quality: "publish" | "hold"and a one-sentencereason. We treat this as a hint, not a decision.
We set responseMimeType to application/json and temperature to 0.1. Even so, the parser has to be forgiving:
def parse_answer(text: str) -> dict:
    text = re.sub(r"^```(?:json)?\s*|\s*```$", "", text.strip())
    try:
        # strict=False allows raw newlines inside string values
        return json.loads(text, strict=False)
    except json.JSONDecodeError:
        # the answer was cut off: keep everything up to the last closed field
        if '",' not in text:
            raise
        cut = text[: text.rfind('",')] + '"}'
        return json.loads(cut, strict=False)
Two failure modes show up in practice. The model sometimes wraps JSON in a Markdown fence despite the MIME type. And sometimes the output stops mid-field when it hits the token limit. Truncating to the last complete field loses one value but keeps the profile, which is a better trade than throwing away the whole answer.
Rate limits are handled the boring way: on HTTP 429, sleep 15, 30, 45 seconds and retry, up to five attempts. Between CVs we pause a few seconds, and results are written to a JSON file after every item, so a crash in the middle of a batch never repeats finished work.
Layer two: scrub every value, twice
The prompt says, in capital letters, never to include phone numbers, emails, URLs or the person's name. The model follows this most of the time. "Most of the time" is not good enough for something that becomes a public page.
So every string value goes through a regular expression before it is saved:
PII_RE = re.compile(
    r"(\+?\d[\d\s().-]{8,}\d)"            # phone-like digit runs
    r"|([\w.+-]+@[\w-]+\.[\w.]+)"          # emails
    r"|(https?://\S+|www\.\S+"             # links
    r"|linkedin\.com/\S+|t\.me/\S+)",      # profile handles
    re.I,
)

def scrub(value):
    if isinstance(value, str):
        return PII_RE.sub("", value).strip()
    return value

answer = {k: scrub(v) for k, v in answer.items()}
The phone pattern is deliberately greedy: ten or more digits with spaces, dots, dashes or brackets in between. It will occasionally eat something that was not a phone number, such as a long ID. For a public profile that is the right direction to be wrong in.
The scrub runs once after the model answers and again when the update is written to the database. The second pass exists because the apply step can receive data from more than one producer (a batch script, a moderation API, a manual fix), and none of them should be trusted to have cleaned their input.
What the regex cannot catch is a name written in plain words. That one we leave to the prompt plus the fact that the public profile has no "name" field at all. The safest field is the one that does not exist.
Layer three: a validation gate that ignores the model's opinion
The final step decides whether the profile goes live. It does not look at the model's quality field. It looks at the data:
def decide(update: dict) -> tuple[bool, str]:
    title = clean(update.get("title") or "")
    about = clean(update.get("about") or "")
    skills = clean(update.get("skills") or "")
    if title and len(about) >= 200 and skills:
        return True, ""
    return False, update.get("reason") or (
        "Upload a readable PDF or fill in title, skills and about manually."
    )
A headline, a summary of at least 200 characters and a skills list: that is enough for an employer to decide whether to look closer. If all three exist, we publish, even when the model hesitated about dates or gaps. Early on we trusted the hold verdict, and good CVs sat in the queue because the model found a two-month gap "suspicious".
The other fields are validated one by one and simply dropped if they do not fit. experience_years must parse as an integer. relocation is normalised from true, "true", "True" or 1. desired_format must be one of the three allowed values. Lists become comma-separated strings; history and education become newline-separated lines.
for field in FIELDS:
    v = update.get(field)
    if v in (None, ""):
        continue
    if field == "experience_years":
        try:
            v = int(v)
        except (TypeError, ValueError):
            continue
    elif field == "desired_format" and v not in ALLOWED_FORMATS:
        continue
    else:
        v = clean(v, "\n" if field in MULTILINE else ", ")
    values[field] = v
A missing or invalid optional field never blocks publication. It just stays as the candidate typed it.
What happens to the ones that fail
Before we had the gate, a CV that could not be structured stayed in pending forever. The candidate saw "under review" and nothing else.
Now a failed profile is returned to the author straight away with a status of rejected, a moderation note with the reason, and a notification that links to the CV section of their account. A very short CV with an empty form does not even reach the model: if the text is under 300 characters and the "about" field is under 200, the script holds it with "the file is not readable and the profile is empty" and saves an API call.
Re-running the pipeline is safe. Already published profiles can be rewritten with a newer, better version, but a new version that fails the gate never takes an existing profile offline. And the "your CV is published" notification is sent only the first time.
What we learned
- Ask the model for JSON with bounded fields, then write a parser that survives fences and truncation anyway.
- Give the model the current date. Otherwise it will argue with your candidates' calendars.
- Never let the LLM be the last line of defence for personal data. Scrub with plain regular expressions, and scrub again at the write boundary.
- Do not ship the model's verdict. Ship a rule over the data that a human can read in one line.
- Make the failure path as good as the success path: a clear reason and a way to fix it beats an eternal "pending".
We use this at SpinHire, a job board for the iGaming industry (https://spinhire.io).
About the author
- SpinHire (spinhire.io) is a job board built only for the iGaming industry: casino, sports betting, game studios, affiliates, payments and compliance. We index 6,600+ live roles from 430+ companies every 6 hours and keep the data open: a public jobs API without a key (CC BY 4.0), XML and RSS feeds, and an MCP server for AI assistants. Here we write about building that index, iGaming tech careers and developer salaries.
Comments
Join the discussionNo comments yet. Be the first to comment.